Observability for AI Swarms: Monitoring Agent Latency, Token Spikes, and Infinite Loops
A production guide on implementing OpenTelemetry distributed tracing, real-time loop detection, and Grafana dashboards for autonomous multi-agent software swarms.
The $300 Infinite Loop That Burned Cash in 20 Minutes
In early 2024, during an automated nightly test migration run, our team experienced an incident that every AI DevOps lead dreads. An autonomous Coder Agent encountered an obscure TypeScript compiler error regarding a missing type definition. Instead of escalating to a human, the agent entered an unmonitored self-correction loop.
The Coder Agent attempted to fix the error by adding an import. The Compiler Agent rejected the build. The Coder Agent attempted to fix the rejected build by modifying a config file. The Compiler Agent rejected it again. Over the next 20 minutes, the two agents executed 412 rapid-fire turns back and forth, consuming over 22 million tokens and racking up nearly $300 in API charges before a developer manually killed the process.
When we investigated our APM dashboards (Datadog and Prometheus), we realized our monitoring tools were completely blind to multi-agent dynamics. Traditional APM monitors CPU, RAM, and HTTP request status codes; it cannot see agent conversation trees, cyclic tool invocations, or runaway token consumption. That expensive lesson drove us to build a comprehensive Observability Architecture for AI swarms.
The Three Pillars of Multi-Agent Observability: Traces, Tokens, and Tools
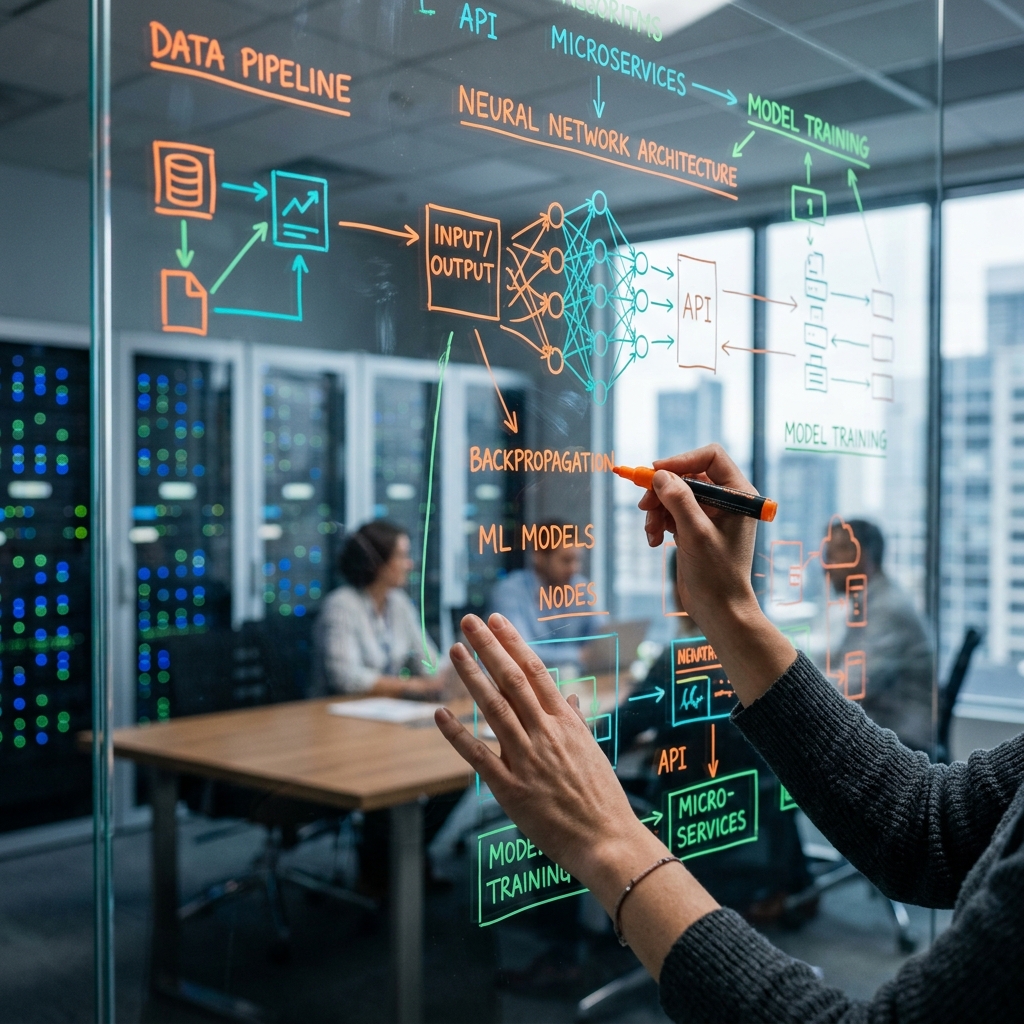
To maintain full operational visibility and cost control over autonomous AI swarms, you must monitor three specialized observability pillars:
1. Distributed Conversation Traces (Directed Acyclic Graphs): In a multi-agent swarm, execution is not linear. A Planner agent spawns three worker agents in parallel, who in turn invoke tools and consult memory. You must trace these interactions as a hierarchical Directed Acyclic Graph (DAG) with parent-child span relationships.
2. Token Velocity and Spend Attribution: Track prompt tokens, completion tokens, reasoning tokens, and cache hits at the individual agent span level. You must know exactly which agent role (e.g. Architect vs Tester) is driving cloud spend.
3. Tool Call Health and Latency: Monitor external tool execution times, exit codes, and payload sizes. If a database query tool or compiler runner begins timing out, the orchestrator must detect the anomaly immediately.
Implementing OpenTelemetry Spans for Multi-Agent Workflows
Ruflo natively implements the OpenTelemetry (OTel) semantic conventions for Generative AI. Every agent task is initialized as a root trace, and every subsequent thought, tool invocation, and memory query is recorded as a structured span.
Each span records standardized metadata attributes: `gen_ai.system: 'ruflo'`, `gen_ai.agent.role: 'developer'`, `gen_ai.model: 'claude-3-7-sonnet'`, `gen_ai.usage.input_tokens: 3420`, `gen_ai.usage.output_tokens: 412`, and `gen_ai.tool.name: 'execute_compiler'`.
Because Ruflo exports traces using the standard OpenTelemetry Protocol (OTLP over gRPC/HTTP), you can stream live telemetry directly to your existing monitoring stack—including Jaeger, Grafana Tempo, Datadog, or Honeycomb—with zero vendor lock-in.
Real-Time Loop Detection Algorithms and Automated Circuit Breakers
To prevent catastrophic runaway spending, Ruflo incorporates an algorithmic Loop Detection Engine operating directly within the orchestration loop:
1. Sliding-Window Tool Pattern Hashing: The orchestrator computes a cryptographic hash of the last 4 tool invocations and their arguments. If the same tool sequence is repeated three times with identical parameters (e.g. `[edit_file, compile, edit_file, compile]`), the loop detector flags an execution anomaly.
2. Semantic Repetition Thresholds: Ruflo compares the cosine similarity between consecutive agent thought traces. If an agent repeats the same reasoning sentences without making forward progress, the system triggers a circuit breaker.
3. Automated Fallback Protocol: When a loop is detected, Ruflo instantly halts the agent, logs a detailed diagnostic trace, executes an atomic memory rollback, and alerts human operators via Slack or CLI modal.
Building Custom Grafana Dashboards for Swarm Health and Spend
Ruflo includes pre-built Grafana dashboard templates that provide real-time operational visibility into your AI infrastructure:
- Executive Spend Dashboard: Live daily/monthly token burn rates broken down by team, project repository, and model provider.
- Swarm Health Matrix: P95 and P99 latency percentiles across all agent roles, compiler pass rates, and consensus voting efficiency.
- Error and Anomaly Heatmaps: Real-time visualization of tool call failures, rate limit throttling events, and circuit breaker trip counts.
With these dashboards on your engineering display screens, your team can operate autonomous AI swarms with complete peace of mind.
Conclusion & Key Takeaways: Visibility as the Prerequisite for Autonomy
You cannot safely scale what you cannot observe. As software engineering organizations transition from interactive single-agent coding to autonomous, long-running agent swarms, robust observability is not an optional luxury—it is an absolute operational necessity.
Summary of Essential Takeaways:
- Adopt OpenTelemetry semantic conventions for distributed multi-agent tracing.
- Implement algorithmic loop detection and automated circuit breakers to eliminate runaway token costs.
- Track spend, latency, and tool health at the granular agent span level.
- Connect telemetry streams to standard platforms like Grafana and Datadog for unified DevOps visibility.
By implementing comprehensive observability with Ruflo, you ensure your autonomous AI swarms deliver maximum engineering velocity with zero operational surprises.
Frequently asked questions
No. Ruflo's telemetry exporter operates asynchronously in a lightweight background worker, adding zero latency to model inference cycles.
Yes! Because Ruflo supports standard OTLP (OpenTelemetry Protocol), it connects seamlessly to Datadog, New Relic, Honeycomb, and Grafana Cloud.
By default, Ruflo triggers a circuit breaker if an agent executes the exact same tool and argument sequence 3 times without making progress.
Yes. Ruflo's governance engine allows administrators to configure hard spending caps per user, team, or repository.
You can configure data redaction rules in `.ruflo/telemetry.json` to hash or mask code diffs and file paths in external trace collectors.
Yes! Ruflo includes ready-to-import Grafana dashboard JSON definitions in our official GitHub repository under `/dashboards`.